

Autoencoder
Neural network that learns efficient data encoding in an unsupervised manner
- 15 min read
- 5 chapters

Related on Lably
Through Neural network (machine learning), Unsupervised learning and Machine learning
Variants exist which aim to make the learned representations assume useful properties. Examples are regularized autoencoders (sparse, denoising and contractive autoencoders), which are effective in learning representations for subsequent classification tasks, and variational autoencoders, which can be used as generative models. Autoencoders are applied to many problems, including facial recognition, feature detection, anomaly detection, and learning the meaning of words. In terms of data synthesis, autoencoders can also be used to randomly generate new data that is similar to the input (training) data.
Mathematical principles
Definition
An autoencoder is defined by the following components:
Two sets: the space of encoded messages ; the space of decoded messages . Typically and are Euclidean spaces, that is, with
Two parametrized families of functions: the encoder family , parametrized by ; the decoder family , parametrized by .
For any , we usually write , and refer to it as the code, the latent variable, latent representation, latent vector, etc. Conversely, for any , we usually write , and refer to it as the (decoded) message.
Usually, both the encoder and the decoder are defined as multilayer perceptrons (MLPs). For example, a one-layer-MLP encoder is:
where is an element-wise activation function, is a "weight" matrix, and is a "bias" vector.
Training an autoencoder
An autoencoder, by itself, is simply a tuple of two functions. To judge its quality, we need a task. A task is defined by a reference probability distribution over , and a "reconstruction quality" function , such that measures how much differs from .
With those, we can define the loss function for the autoencoder asThe optimal autoencoder for the given task is then . The search for the optimal autoencoder can be accomplished by any mathematical optimization technique, but usually by gradient descent. This search process is referred to as "training the autoencoder".
In most situations, the reference distribution is just the empirical distribution given by a dataset , so that
where is the Dirac measure, the quality function is just loss: , and is the Euclidean norm. Then the problem of searching for the optimal autoencoder is just a least-squares optimization:
Interpretation
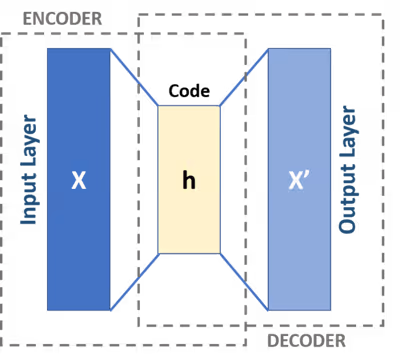
An autoencoder has two main parts: an encoder that maps the message to a code, and a decoder that reconstructs the message from the code. An optimal autoencoder would perform as close to perfect reconstruction as possible, with "close to perfect" defined by the reconstruction quality function .
The simplest way to perform the copying task perfectly would be to duplicate the signal. To suppress this behavior, the code space usually has fewer dimensions than the message space .
Such an autoencoder is called undercomplete. It can be interpreted as compressing the message, or reducing its dimensionality.
At the limit of an ideal undercomplete autoencoder, every possible code in the code space is used to encode a message that really appears in the distribution , and the decoder is also perfect: . This ideal autoencoder can then be used to generate messages indistinguishable from real messages, by feeding its decoder arbitrary code and obtaining , which is a message that really appears in the distribution .
If the code space has dimension larger than (overcomplete), or equal to, the message space , or the hidden units are given enough capacity, an autoencoder can learn the identity function and become useless. However, experimental results found that overcomplete autoencoders might still learn useful features.
In the ideal setting, the code dimension and the model capacity could be set on the basis of the complexity of the data distribution to be modeled. A standard way to do so is to add modifications to the basic autoencoder, to be detailed below.
Sign in to keep reading
4 more chapters are free with a Lably account.
Variations
Variational autoencoder (VAE)
Variational autoencoders (VAEs) belong to the families of variational Bayesian methods. Despite the architectural similarities with basic autoencoders, VAEs are architected with different goals and have a different mathematical formulation. The latent space is, in this case, composed of a mixture of distributions instead of fixed vectors.
Given an input dataset characterized by an unknown probability function and a multivariate latent encoding vector , the objective is to model the data as a distribution , with defined as the set of the network parameters so that .
Sparse autoencoder (SAE)
Inspired by the sparse coding hypothesis in neuroscience, sparse autoencoders (SAE) are variants of autoencoders, such that the codes for messages tend to be sparse codes, that is, is close to zero in most entries. Sparse autoencoders may include more (rather than fewer) hidden units than inputs, but only a small number of the hidden units are allowed to be active at the same time. Encouraging sparsity improves performance on classification tasks.
There are two main ways to enforce sparsity. One way is to simply clamp all but the highest-k activations of the latent code to zero. This is the k-sparse autoencoder.
The k-sparse autoencoder inserts the following "k-sparse function" in the latent layer of a standard autoencoder:where if ranks in the top k, and 0 otherwise.
Backpropagating through is simple: set gradient to 0 for entries, and keep gradient for entries. This is essentially a generalized ReLU function.
The other way is a relaxed version of the k-sparse autoencoder. Instead of forcing sparsity, we add a sparsity regularization loss, then optimize forwhere measures how much sparsity we want to enforce.
Let the autoencoder architecture have layers. To define a sparsity regularization loss, we need a "desired" sparsity for each layer, a weight for how much to enforce each sparsity, and a function to measure how much two sparsities differ.
For each input , let the actual sparsity of activation in each layer bewhere is the activation in the -th neuron of the -th layer upon input .
The sparsity loss upon input for one layer is , and the sparsity regularization loss for the entire autoencoder is the expected weighted sum of sparsity losses:Typically, the function is either the Kullback–Leibler (KL) divergence, as
or the L1 loss, as , or the L2 loss, as .
Alternatively, the sparsity regularization loss may be defined without reference to any "desired sparsity", but simply force as much sparsity as possible. In this case, one can define the sparsity regularization loss as where is the activation vector in the -th layer of the autoencoder. The norm is usually the L1 norm (giving the L1 sparse autoencoder) or the L2 norm (giving the L2 sparse autoencoder).
Denoising autoencoder (DAE)
Denoising autoencoders (DAE) try to achieve a good representation by changing the reconstruction criterion.
A DAE, originally called a "robust autoassociative network" by Mark A. Kramer, is trained by intentionally corrupting the inputs of a standard autoencoder during training. A noise process is defined by a probability distribution over functions . That is, the function takes a message , and corrupts it to a noisy version . The function is selected randomly, with a probability distribution .
Given a task , the problem of training a DAE is the optimization problem:That is, the optimal DAE should take any noisy message and attempt to recover the original message without noise, thus the name "denoising".
Usually, the noise process is applied only during training and testing, not during downstream use.
The use of DAE depends on two assumptions:
- There exist representations to the messages that are relatively stable and robust to the type of noise we are likely to encounter;
- The said representations capture structures in the input distribution that are useful for our purposes.
Example noise processes include:
- additive isotropic Gaussian noise,
- masking noise (a fraction of the input is randomly chosen and set to 0)
- salt-and-pepper noise (a fraction of the input is randomly chosen and randomly set to its minimum or maximum value).
Contractive autoencoder (CAE)
A contractive autoencoder (CAE) adds the contractive regularization loss to the standard autoencoder loss:where measures how much contractive-ness we want to enforce. The contractive regularization loss itself is defined as the expected square of Frobenius norm of the Jacobian matrix of the encoder activations with respect to the input:To understand what measures, note the factfor any message , and small variation in it. Thus, if is small, it means that a small neighborhood of the message maps to a small neighborhood of its code. This is a desired property, as it means small variation in the message leads to small, perhaps even zero, variation in its code, like how two pictures may look the same even if they are not exactly the same.
The CAE can be understood as an infinitesimal limit of DAE: in the limit of small Gaussian input noise, DAEs make the reconstruction function resist small but finite-sized input perturbations, while CAEs make the extracted features resist infinitesimal input perturbations. However, while DAEs encourage robustness of reconstruction, CAEs encourage robustness of representation. Additionally, DAEs' robustness is obtained stochastically, by having various corrupted versions of a training point aim for an identical reconstruction. In contrast, CAEs' robustness to small perturbations is obtained analytically by penalizing the Frobenius norm of the encoder Jacobian, , evaluated at the training samples.
Minimum description length autoencoder (MDL-AE)
A minimum description length autoencoder (MDL-AE) is an advanced variation of the traditional autoencoder, which leverages principles from information theory, specifically the Minimum Description Length (MDL) principle. The MDL principle posits that the best model for a dataset is the one that provides the shortest combined encoding of the model and the data. In the context of autoencoders, this principle is applied to ensure that the learned representation is not only compact but also interpretable and efficient for reconstruction.
The MDL-AE seeks to minimize the total description length of the data, which includes the size of the latent representation (code length) and the error in reconstructing the original data. The objective can be expressed as , where represents the length of the compressed latent representation and denotes the reconstruction error.
Concrete autoencoder (CAE)
The concrete autoencoder is designed for discrete feature selection. A concrete autoencoder forces the latent space to consist only of a user-specified number of features. The concrete autoencoder uses a continuous relaxation of the categorical distribution to allow gradients to pass through the feature selector layer, which makes it possible to use standard backpropagation to learn an optimal subset of input features that minimize reconstruction loss.
Advantages of depth
Autoencoders are often trained with a single-layer encoder and a single-layer decoder, but using many-layered (deep) encoders and decoders offers many advantages.
- Depth can exponentially reduce the computational cost of representing some functions.
- Depth can exponentially decrease the amount of training data needed to learn some functions.
- Experimentally, deep autoencoders yield better compression compared to shallow or linear autoencoders.
- Depth allows for advantages over traditional methods as one can show that after training single layer linear autoencoders have a latent space whose vectors span the same subspace as the eigenvectors found in Principal component analysis.
Training
Geoffrey Hinton developed the deep belief network technique for training many-layered deep autoencoders. His method involves treating each neighboring set of two layers as a restricted Boltzmann machine so that pretraining approximates a good solution, then using backpropagation to fine-tune the results.
Researchers have debated whether joint training (i.e. training the whole architecture together with a single global reconstruction objective to optimize) would be better for deep auto-encoders. A 2015 study showed that joint training learns better data models along with more representative features for classification as compared to the layerwise method. However, their experiments showed that the success of joint training depends heavily on the regularization strategies adopted.
History
(Oja, 1982) noted that PCA is equivalent to a neural network with one hidden layer with identity activation function. In the language of autoencoding, the input-to-hidden module is the encoder, and the hidden-to-output module is the decoder. Subsequently, in (Baldi and Hornik, 1989) and (Kramer, 1991) generalized PCA to autoencoders, a technique which they termed "nonlinear PCA".
Immediately after the resurgence of neural networks in the 1980s, it was suggested in 1986 that a neural network be put in "auto-association mode". This was then implemented in (Harrison, 1987) and (Elman, Zipser, 1988) for speech and in (Cottrell, Munro, Zipser, 1987) for images. In (Hinton, Salakhutdinov 2006), deep belief networks were developed. These train a pair restricted Boltzmann machines as encoder-decoder pairs, then train another pair on the latent representation of the first pair, and so on.
The first applications of AE date to early 1990s. Their most traditional application was dimensionality reduction or feature learning, but the concept became widely used for learning generative models of data. Some of the most powerful AIs in the 2010s involved autoencoder modules as a component of larger AI systems, such as VAE in Stable Diffusion, discrete VAE in Transformer-based image generators like DALL-E 1, etc.
During the early days, when the terminology was uncertain, the autoencoder has also been called identity mapping, auto-associating, self-supervised backpropagation, or Diabolo network.
Applications
The two main applications of autoencoders are dimensionality reduction and information retrieval (or associative memory), but modern variations have been applied to other tasks.
Dimensionality reduction
Dimensionality reduction was one of the first deep learning applications.
For Hinton's 2006 study, he pretrained a multi-layer autoencoder with a stack of RBMs and then used their weights to initialize a deep autoencoder with gradually smaller hidden layers until hitting a bottleneck of 30 neurons. The resulting 30 dimensions of the code yielded a smaller reconstruction error compared to the first 30 components of a principal component analysis (PCA), and learned a representation that was qualitatively easier to interpret, clearly separating data clusters.
Reducing dimensions can improve performance on tasks such as classification. Indeed, the hallmark of dimensionality reduction is to place semantically related examples near each other.
Principal component analysis
If linear activations are used, or only a single sigmoid hidden layer, then the optimal solution to an autoencoder is strongly related to principal component analysis (PCA). The weights of an autoencoder with a single hidden layer of size (where is less than the size of the input) span the same vector subspace as the one spanned by the first principal components, and the output of the autoencoder is an orthogonal projection onto this subspace. The autoencoder weights are not equal to the principal components, and are generally not orthogonal, yet the principal components may be recovered from them using the singular value decomposition.
However, the potential of autoencoders resides in their non-linearity, allowing the model to learn more powerful generalizations compared to PCA, and to reconstruct the input with significantly lower information loss.
Information retrieval
Information retrieval benefits particularly from dimensionality reduction in that search can become more efficient in certain kinds of low dimensional spaces. Autoencoders were indeed applied to semantic hashing, proposed by Salakhutdinov and Hinton in 2007. By training the algorithm to produce a low-dimensional binary code, all database entries could be stored in a hash table mapping binary code vectors to entries. This table would then support information retrieval by returning all entries with the same binary code as the query, or slightly less similar entries by flipping some bits from the query encoding.
Anomaly detection
Another application for autoencoders is anomaly detection. By learning to replicate the most salient features in the training data under some of the constraints described previously, the model is encouraged to learn to precisely reproduce the most frequently observed characteristics. When facing anomalies, the model should worsen its reconstruction performance. In most cases, only data with normal instances are used to train the autoencoder; in others, the frequency of anomalies is small compared to the observation set so that its contribution to the learned representation could be ignored. After training, the autoencoder will accurately reconstruct "normal" data, while failing to do so with unfamiliar anomalous data. Reconstruction error (the error between the original data and its low dimensional reconstruction) is used as an anomaly score to detect anomalies. Typically, this means that on a validation set the empirical distribution of reconstruction errors is recorded and then (e.g.) the empirical 95-percentile is taken as threshold to flag anomalous data points: . Since the threshold is an empirical quantile estimate, there is an inherent difficulty with "correctly" setting this threshold: In many cases the distribution of the empirical quantile is asymptotically a normal distribution with the probability density at the quantile. This means that the variance grows if an extreme quantile is considered (because is small there). This means that there is a, potentially, a big uncertainty in what is the right choice for the threshold since it is estimated from a validation set.
Recent literature has however shown that certain autoencoding models can, counterintuitively, be very good at reconstructing anomalous examples and consequently not able to reliably perform anomaly detection. Intuitively, this can be understood by considering those one layer auto encoders which are related to PCA - also in this case there can be perfect rein reconstructions for points which are far away from the data region but which lie on a principal component axis.
It is best to analyze if the anomalies which are flagged by the auto encoder are true anomalies. In this sense all the metrics in Evaluation of binary classifiers can be considered. The fundamental challenge which comes with the unsupervised (self-supervised) learning setting is, that labels for rare events do not exist (in which case the labels first have to be gathered and the data set will be imbalanced) or anomaly indicating labels are very rare, introducing larger confidence intervals for these performance estimates.
Image processing
The characteristics of autoencoders are useful in image processing.
One example can be found in lossy image compression, where autoencoders outperformed other approaches and proved competitive against JPEG 2000.
Another useful application of autoencoders in image preprocessing is image denoising.
Autoencoders found use in more demanding contexts such as medical imaging where they have been used for image denoising as well as super-resolution. In image-assisted diagnosis, experiments have applied autoencoders for breast cancer detection and for modelling the relation between the cognitive decline of Alzheimer's disease and the latent features of an autoencoder trained with MRI.
Drug discovery
In 2019 molecules generated with variational autoencoders were validated experimentally in mice.
Popularity prediction
Recently, a stacked autoencoder framework produced promising results in predicting popularity of social media posts, which is helpful for online advertising strategies.
Machine translation
Autoencoders have been applied to machine translation, which is usually referred to as neural machine translation (NMT). Unlike traditional autoencoders, the output does not match the input - it is in another language. In NMT, texts are treated as sequences to be encoded into the learning procedure, while on the decoder side sequences in the target language(s) are generated. Language-specific autoencoders incorporate further linguistic features into the learning procedure, such as Chinese decomposition features. Machine translation is rarely still done with autoencoders, due to the availability of more effective transformer networks.
Communication Systems
Autoencoders in communication systems are important because they help in encoding data into a more resilient representation for channel impairments, which is crucial for transmitting information while minimizing errors. In Addition, AE-based systems can optimize end-to-end communication performance. This approach can solve the several limitations of designing communication systems such as the inherent difficulty in accurately modeling the complex behavior of real-world channels.