

Central limit theorem
Fundamental theorem in probability theory and statistics
- 21 min read
- 8 chapters
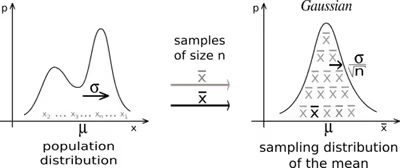

Learn it on Lably
The theorem is a key concept in probability theory because it implies that probabilistic and statistical methods that work for normal distributions can be applicable to many problems involving other types of distributions.
This theorem has seen many changes during the formal development of probability theory. Previous versions of the theorem date back to 1811, but in its modern form it was only precisely stated in the 1920s.
In statistics, the CLT can be stated as: let denote a statistical sample of size from a population with expected value (average) and finite positive variance , and let denote the sample mean (which is itself a random variable). Then the limit as of the distribution of is a normal distribution with mean and variance .
In other words, suppose that a large sample of observations is obtained, each observation being randomly produced in a way that does not depend on the values of the other observations, and the average (arithmetic mean) of the observed values is computed. If this procedure is performed many times, resulting in a collection of observed averages, the central limit theorem says that if the sample size is large enough, the probability distribution of these averages will closely approximate a normal distribution.
The central limit theorem has several variants. In its common form, the random variables must be independent and identically distributed (i.i.d.). This requirement can be weakened; convergence of the mean to the normal distribution also occurs for non-identical distributions or for non-independent observations if they comply with certain conditions.
The earliest version of this theorem, that the normal distribution may be used as an approximation to the binomial distribution, is the de Moivre–Laplace theorem.
Independent sequences
Classical CLT
Let be a sequence of i.i.d. random variables having a distribution with expected value given by and finite variance given by Suppose we are interested in the sample average
By the law of large numbers, the sample average converges almost surely (and therefore also converges in probability) to the expected value as
The classical central limit theorem describes the size and the distributional form of the stochastic fluctuations around the deterministic number during this convergence. More precisely, it states that as gets larger, the distribution of the normalized mean , i.e. the difference between the sample average and its limit scaled by the factor , approaches the normal distribution with mean and variance For large enough the distribution of gets arbitrarily close to the normal distribution with mean and variance
The usefulness of the theorem is that the distribution of approaches normality regardless of the shape of the distribution of the individual Formally, the theorem can be stated as follows:
Lindeberg–Lévy CLT—Suppose is a sequence of i.i.d. random variables with and Then, as approaches infinity, the random variables converge in distribution to a normal :
In the case convergence in distribution means that the cumulative distribution functions of converge pointwise to the cdf of the distribution: for every real number
where is the standard normal cdf evaluated at The convergence is uniform in in the sense that
where denotes the supremum (i.e. least upper bound) of the set.
Lyapunov CLT
In this variant of the central limit theorem the random variables have to be independent, but not necessarily identically distributed. The theorem also requires that random variables have moments of some order , and that the rate of growth of these moments is limited by the Lyapunov condition given below.
Lyapunov CLT—Suppose is a sequence of independent random variables, each with finite expected value and variance . Define
If for some , Lyapunov's condition
is satisfied, then a sum of converges in distribution to a standard normal random variable, as goes to infinity:
In practice it is usually easiest to check Lyapunov's condition for .
If a sequence of random variables satisfies Lyapunov's condition, then it also satisfies Lindeberg's condition. The converse implication, however, does not hold.
Lindeberg (-Feller) CLT
In the same setting and with the same notation as above, the Lyapunov condition can be replaced with the following weaker one (from Lindeberg in 1920).
Suppose that for every ,
where is the indicator function. Then the distribution of the standardized sums
converges towards the standard normal distribution .
CLT for the sum of a random number of random variables
Rather than summing an integer number of random variables and taking , the sum can be of a random number of random variables, with conditions on . For example, the following theorem is Corollary 4 of Robbins (1948). It assumes that is asymptotically normal (Robbins also developed other conditions that lead to the same result).
Robbins CLT—Let be independent, identically distributed random variables with and , and let be a sequence of non-negative integer-valued random variables that are independent of . Assume for each that and
where denotes convergence in distribution and is the normal distribution with mean 0, variance 1. Then
Multidimensional CLT
Proofs that use characteristic functions can be extended to cases where each individual is a random vector in , with mean vector and covariance matrix (among the components of the vector), and these random vectors are independent and identically distributed. The multidimensional central limit theorem states that when scaled, sums converge to a multivariate normal distribution. Summation of these vectors is done component-wise.
For let
be independent random vectors. The sum of the random vectors is
and their average is
Therefore,
The multivariate central limit theorem states that
where the covariance matrix is equal to
The multivariate central limit theorem can be proved using the Cramér–Wold theorem.
The rate of convergence is given by the following Berry–Esseen type result:
Theorem—Let be independent -valued random vectors, each having mean zero. Write and assume is invertible. Let be a -dimensional Gaussian with the same mean and same covariance matrix as . Then for all convex sets ,
where is a universal constant, , and denotes the Euclidean norm on .
It is unknown whether the factor is necessary.
Sign in to keep reading
7 more chapters are free with a Lably account.
The generalized central limit theorem
The generalized central limit theorem (GCLT) was an effort of multiple mathematicians (Sergei Bernstein, Jarl Waldemar Lindeberg, Paul Lévy, William Feller, Andrey Kolmogorov, and others) over the period from 1920 to 1937. The first published complete proof of the GCLT was in 1937 by Paul Lévy in French. An English language version of the complete proof of the GCLT is available in the translation of Boris Vladimirovich Gnedenko and Kolmogorov's 1954 book.
The statement of the GCLT is as follows:
Statement of GCLT—A non-degenerate random variable Z is α-stable for some 0 < α ≤ 2 if and only if there is an independent, identically distributed sequence of random variables X1, X2, X3, ..., and constants an > 0, bn ∈ ℝ with Here, '→' means the sequence of random variable sums converges in distribution; i.e., the corresponding distributions satisfy Fn(y) → F(y) at all continuity points of F.
In other words, if sums of independent, identically distributed random variables converge in distribution to some Z, then Z must be a stable distribution.
Dependent processes
CLT under weak dependence
A useful generalization of a sequence of independent, identically distributed random variables is a mixing random process in discrete time; "mixing" means, roughly, that random variables temporally far apart from one another are nearly independent. Several kinds of mixing are used in ergodic theory and probability theory. See especially strong mixing (also called α-mixing) defined by where is so-called strong mixing coefficient.
A simplified formulation of the central limit theorem under strong mixing is:
Theorem—Suppose that is stationary and -mixing with and that and . Denote , then the limit
exists, and if then converges in distribution to .
In fact,
where the series converges absolutely.
The assumption cannot be omitted, since the asymptotic normality fails for where are another stationary sequence.
There is a stronger version of the theorem: the assumption is replaced with , and the assumption is replaced with
Existence of such ensures the conclusion. For encyclopedic treatment of limit theorems under mixing conditions see (Bradley 2007).
Martingale difference CLT
Theorem—Let a martingale satisfy
- in probability as n → ∞,
- for every ε > 0, as n → ∞,
then converges in distribution to as .
Remarks
Proof of classical CLT
The central limit theorem has a proof using characteristic functions. It is similar to the proof of the (weak) law of large numbers.
Assume are independent and identically distributed random variables, each with mean and finite variance . The sum has mean and variance . Consider the random variable
where the last step defines the new random variables , each with zero mean and unit variance (). The characteristic function of is given by
where the last step relies on the fact that all of the are identically distributed. The characteristic function of is, by Taylor's theorem,
where is "little o notation" for some function of that goes to zero more rapidly than . By the limit of the exponential function (), the characteristic function of equals
All of the higher order terms vanish in the limit . The right hand side equals the characteristic function of a standard normal distribution , which implies through Lévy's continuity theorem that the distribution of will approach as . Therefore, the sample average
is such that
converges to the normal distribution , from which the central limit theorem follows.
Convergence to the limit
The central limit theorem gives only an asymptotic distribution. As an approximation for a finite number of observations, it provides a reasonable approximation only when close to the peak of the normal distribution; it requires a very large number of observations to stretch into the tails.
The convergence in the central limit theorem is uniform because the limiting cumulative distribution function is continuous. If the third central moment exists and is finite, then the speed of convergence is at least on the order of (see Berry–Esseen theorem). Stein's method can be used not only to prove the central limit theorem, but also to provide bounds on the rates of convergence for selected metrics.
The convergence to the normal distribution is monotonic, in the sense that the entropy of increases monotonically to that of the normal distribution.
The central limit theorem applies in particular to sums of independent and identically distributed discrete random variables. A sum of discrete random variables is still a discrete random variable, so that we are confronted with a sequence of discrete random variables whose cumulative probability distribution function converges towards a cumulative probability distribution function corresponding to a continuous variable (namely that of the normal distribution). This means that if we build a histogram of the realizations of the sum of n independent identical discrete variables, the piecewise-linear curve that joins the centers of the upper faces of the rectangles forming the histogram converges toward a Gaussian curve as n approaches infinity; this relation is known as de Moivre–Laplace theorem. The binomial distribution article details such an application of the central limit theorem in the simple case of a discrete variable taking only two possible values.
Common misconceptions
Studies have shown that the central limit theorem is subject to several common but serious misconceptions, some of which appear in widely used textbooks. These include:
- The misconceived belief that the theorem applies to random sampling of any variable, rather than to the mean values (or sums) of iid random variables extracted from a population by repeated sampling. That is, the theorem assumes the random sampling produces a sampling distribution formed from different values of means (or sums) of such random variables.
- The misconceived belief that the theorem ensures that random sampling leads to the emergence of a normal distribution for sufficiently large samples of any random variable, regardless of the population distribution. In reality, such sampling asymptotically reproduces the properties of the population, an intuitive result underpinned by the Glivenko–Cantelli theorem.
- The misconceived belief that the theorem leads to a good approximation of a normal distribution for sample sizes greater than around 30, allowing reliable inferences regardless of the nature of the population. In reality, this empirical rule of thumb has no valid justification, and can lead to seriously flawed inferences. See Z-test for where the approximation holds.
Relation to the law of large numbers
The law of large numbers as well as the central limit theorem are partial solutions to a general problem: "What is the limiting behavior of Sn as n approaches infinity?" In mathematical analysis, asymptotic series are one of the most popular tools employed to approach such questions.
Suppose we have an asymptotic expansion of :
Dividing both parts by φ1(n) and taking the limit will produce a1, the coefficient of the highest-order term in the expansion, which represents the rate at which f(n) changes in its leading term.
Informally, one can say: "f(n) grows approximately as a1φ1(n)". Taking the difference between f(n) and its approximation and then dividing by the next term in the expansion, we arrive at a more refined statement about f(n):
Here one can say that the difference between the function and its approximation grows approximately as a2φ2(n). The idea is that dividing the function by appropriate normalizing functions, and looking at the limiting behavior of the result, can tell us much about the limiting behavior of the original function itself.
Informally, something along these lines happens when the sum, Sn, of independent identically distributed random variables, X1, ..., Xn, is studied in classical probability theory. If each Xi has finite mean μ, then by the law of large numbers, Sn/n → μ. If in addition each Xi has finite variance σ2, then by the central limit theorem,
where ξ is distributed as N(0,σ2). This provides values of the first two constants in the informal expansion
In the case where the Xi do not have finite mean or variance, convergence of the shifted and rescaled sum can also occur with different centering and scaling factors:
or informally
Distributions Ξ which can arise in this way are called stable. Clearly, the normal distribution is stable, but there are also other stable distributions, such as the Cauchy distribution, for which the mean or variance are not defined. The scaling factor bn may be proportional to nc, for any c ≥ 1/2; it may also be multiplied by a slowly varying function of n.
The law of the iterated logarithm specifies what is happening "in between" the law of large numbers and the central limit theorem. Specifically it says that the normalizing function √n log log n, intermediate in size between n of the law of large numbers and √n of the central limit theorem, provides a non-trivial limiting behavior.
Alternative statements of the theorem
Density functions
The density of the sum of two or more independent variables is the convolution of their densities (if these densities exist). Thus the central limit theorem can be interpreted as a statement about the properties of density functions under convolution: the convolution of a number of density functions tends to the normal density as the number of density functions increases without bound. These theorems require stronger hypotheses than the forms of the central limit theorem given above. Theorems of this type are often called local limit theorems. See Petrov for a particular local limit theorem for sums of independent and identically distributed random variables.
Characteristic functions
Since the characteristic function of a convolution is the product of the characteristic functions of the densities involved, the central limit theorem has yet another restatement: the product of the characteristic functions of a number of density functions becomes close to the characteristic function of the normal density as the number of density functions increases without bound, under the conditions stated above. Specifically, an appropriate scaling factor needs to be applied to the argument of the characteristic function.
An equivalent statement can be made about Fourier transforms, since the characteristic function is essentially a Fourier transform.
Calculating the variance
Let Sn be the sum of n random variables. Many central limit theorems provide conditions such that Sn/√Var(Sn) converges in distribution to N(0,1) (the normal distribution with mean 0, variance 1) as n → ∞. In some cases, it is possible to find a constant σ2 and function f(n) such that Sn/(σ√n⋅f(n)) converges in distribution to N(0,1) as n→ ∞.
Lemma—Suppose is a sequence of real-valued and strictly stationary random variables with for all , , and . Construct
- If is absolutely convergent, , and then as where .
- If in addition and converges in distribution to as then also converges in distribution to as .
Extensions
Products of positive random variables
The logarithm of a product is simply the sum of the logarithms of the factors. Therefore, when the logarithm of a product of random variables that take only positive values approaches a normal distribution, the product itself approaches a log-normal distribution. Many physical quantities (especially mass or length, which are a matter of scale and cannot be negative) are the products of different random factors, so they follow a log-normal distribution. This multiplicative version of the central limit theorem is sometimes called Gibrat's law.
Whereas the central limit theorem for sums of random variables requires the condition of finite variance, the corresponding theorem for products requires the corresponding condition that the density function be square-integrable.
Beyond the classical framework
Asymptotic normality, that is, convergence to the normal distribution after appropriate shift and rescaling, is a phenomenon much more general than the classical framework treated above, namely, sums of independent random variables (or vectors). New frameworks are revealed from time to time; no single unifying framework is available for now.
Convex body
Theorem—There exists a sequence εn ↓ 0 for which the following holds. Let n ≥ 1, and let random variables X1, ..., Xn have a log-concave joint density f such that f(x1, ..., xn) = f(|x1|, ..., |xn|) for all x1, ..., xn, and E(X2
k) = 1 for all k = 1, ..., n. Then the distribution of
is εn-close to in the total variation distance.
These two εn-close distributions have densities (in fact, log-concave densities), thus, the total variance distance between them is the integral of the absolute value of the difference between the densities. Convergence in total variation is stronger than weak convergence.
An important example of a log-concave density is a function constant inside a given convex body and vanishing outside; it corresponds to the uniform distribution on the convex body, which explains the term "central limit theorem for convex bodies".
Another example: f(x1, ..., xn) = const · exp(−(|x1|α + ⋯ + |xn|α)β) where α > 1 and αβ > 1. If β = 1 then f(x1, ..., xn) factorizes into const · exp (−|x1|α) ... exp(−|xn|α), which means X1, ..., Xn are independent. In general, however, they are dependent.
The condition f(x1, ..., xn) = f(|x1|, ..., |xn|) ensures that X1, ..., Xn are of zero mean and uncorrelated; still, they need not be independent, nor even pairwise independent. By the way, pairwise independence cannot replace independence in the classical central limit theorem.
Here is a Berry–Esseen type result.
Theorem—Let X1, ..., Xn satisfy the assumptions of the previous theorem, then
for all a < b; here C is a universal (absolute) constant. Moreover, for every c1, ..., cn ∈ R such that c2
1 + ⋯ + c2
n = 1,
The distribution of X1 + ⋯ + Xn/√n need not be approximately normal (in fact, it can be uniform). However, the distribution of c1X1 + ⋯ + cnXn is close to (in the total variation distance) for most vectors (c1, ..., cn) according to the uniform distribution on the sphere c2
1 + ⋯ + c2
n = 1.
Lacunary trigonometric series
Theorem (Salem–Zygmund)—Let U be a random variable distributed uniformly on (0,2π), and Xk = rk cos(nkU + ak), where
- nk satisfy the lacunarity condition: there exists q > 1 such that nk + 1 ≥ qnk for all k,
- rk are such that
- 0 ≤ ak < 2π.
Then
converges in distribution to .
Gaussian polytopes
Theorem—Let A1, ..., An be independent random points on the plane R2 each having the two-dimensional standard normal distribution. Let Kn be the convex hull of these points, and Xn the area of Kn Then
converges in distribution to as n tends to infinity.
The same also holds in all dimensions greater than 2.
The polytope Kn is called a Gaussian random polytope.
A similar result holds for the number of vertices (of the Gaussian polytope), the number of edges, and in fact, faces of all dimensions.
Linear functions of orthogonal matrices
A linear function of a matrix M is a linear combination of its elements (with given coefficients), M ↦ tr(AM) where A is the matrix of the coefficients; see Trace (linear algebra)#Inner product.
A random orthogonal matrix is said to be distributed uniformly, if its distribution is the normalized Haar measure on the orthogonal group O(n,R); see Rotation matrix#Uniform random rotation matrices.
Theorem—Let M be a random orthogonal n × n matrix distributed uniformly, and A a fixed n × n matrix such that tr(AA*) = n, and let X = tr(AM). Then the distribution of X is close to in the total variation metric up to 2√3/n − 1.
Subsequences
Theorem—Let random variables X1, X2, ... ∈ L2(Ω) be such that Xn → 0 weakly in L2(Ω) and X
n → 1 weakly in L1(Ω). Then there exist integers n1 < n2 < ⋯ such that
converges in distribution to as k tends to infinity.
Random walk on a crystal lattice
The central limit theorem may be established for the simple random walk on a crystal lattice (an infinite-fold abelian covering graph over a finite graph), and is used for design of crystal structures.
Applications and examples
A simple example of the central limit theorem is rolling many identical, unbiased dice. The distribution of the sum (or average) of the rolled numbers will be well approximated by a normal distribution. Since real-world quantities are often the balanced sum of many unobserved random events, the central limit theorem also provides a partial explanation for the prevalence of the normal probability distribution. It also justifies the approximation of large-sample statistics to the normal distribution in controlled experiments.
Regression
Regression analysis, and in particular ordinary least squares, specifies that a dependent variable depends according to some function upon one or more independent variables, with an additive error term. Various types of statistical inference on the regression assume that the error term is normally distributed. This assumption can be justified by assuming that the error term is actually the sum of many independent error terms; even if the individual error terms are not normally distributed, by the central limit theorem their sum can be well approximated by a normal distribution.
Other illustrations
Given its importance to statistics, a number of papers and computer packages are available that demonstrate the convergence involved in the central limit theorem.
History
Dutch mathematician Henk Tijms writes:
The central limit theorem has an interesting history. The first version of this theorem was postulated by the French-born mathematician Abraham de Moivre who, in a remarkable article published in 1733, used the normal distribution to approximate the distribution of the number of heads resulting from many tosses of a fair coin. This finding was far ahead of its time, and was nearly forgotten until the famous French mathematician Pierre-Simon Laplace rescued it from obscurity in his monumental work Théorie analytique des probabilités, which was published in 1812. Laplace expanded De Moivre's finding by approximating the binomial distribution with the normal distribution. But as with De Moivre, Laplace's finding received little attention in his own time. It was not until the nineteenth century was at an end that the importance of the central limit theorem was discerned, when, in 1901, Russian mathematician Aleksandr Lyapunov defined it in general terms and proved precisely how it worked mathematically. Nowadays, the central limit theorem is considered to be the unofficial sovereign of probability theory.
Sir Francis Galton described the Central Limit Theorem in this way:
I know of scarcely anything so apt to impress the imagination as the wonderful form of cosmic order expressed by the "Law of Frequency of Error". The law would have been personified by the Greeks and deified, if they had known of it. It reigns with serenity and in complete self-effacement, amidst the wildest confusion. The huger the mob, and the greater the apparent anarchy, the more perfect is its sway. It is the supreme law of Unreason. Whenever a large sample of chaotic elements are taken in hand and marshalled in the order of their magnitude, an unsuspected and most beautiful form of regularity proves to have been latent all along.
The actual term "central limit theorem" (in German: "zentraler Grenzwertsatz") was first used by George Pólya in 1920 in the title of a paper. Pólya referred to the theorem as "central" due to its importance in probability theory. According to Le Cam, the French school of probability interprets the word central in the sense that "it describes the behaviour of the centre of the distribution as opposed to its tails". The abstract of the paper On the central limit theorem of calculus of probability and the problem of moments by Pólya in 1920 translates as follows.
The occurrence of the Gaussian probability density 1 = e−x2 in repeated experiments, in errors of measurements, which result in the combination of very many and very small elementary errors, in diffusion processes etc., can be explained, as is well-known, by the very same limit theorem, which plays a central role in the calculus of probability. The actual discoverer of this limit theorem is to be named Laplace; it is likely that its rigorous proof was first given by Tschebyscheff and its sharpest formulation can be found, as far as I am aware of, in an article by Liapounoff. ...
A thorough account of the theorem's history, detailing Laplace's foundational work, as well as Cauchy's, Bessel's and Poisson's contributions, is provided by Hald. Two historical accounts, one covering the development from Laplace to Cauchy, the second the contributions by von Mises, Pólya, Lindeberg, Lévy, and Cramér during the 1920s, are given by Hans Fischer. Le Cam describes a period around 1935. Bernstein presents a historical discussion focusing on the work of Pafnuty Chebyshev and his students Andrey Markov and Aleksandr Lyapunov that led to the first proofs of the CLT in a general setting.
A curious footnote to the history of the Central Limit Theorem is that a proof of a result similar to the 1922 Lindeberg CLT was the subject of Alan Turing's 1934 Fellowship Dissertation for King's College at the University of Cambridge. Only after submitting the work did Turing learn it had already been proved. Consequently, Turing's dissertation was not published.