

Multivariate normal distribution
Generalization of the one-dimensional normal distribution to higher dimensions
- 16 min read
- 4 chapters

Related on Lably
Through Statistics, Normal distribution and Dimension
Definitions
Notation and parametrization
The multivariate normal distribution of a k-dimensional random vector can be written in the following notation:
or to make it explicitly known that is k-dimensional,
with k-dimensional mean vector
such that and . The inverse of the covariance matrix is called the precision matrix, denoted by .
Standard normal random vector
A real random vector is called a standard normal random vector if all of its components are independent and each is a zero-mean unit-variance normally distributed random variable, i.e. if for all .
Centered normal random vector
A real random vector is called a centered normal random vector if there exists a matrix such that has the same distribution as where is a standard normal random vector with components.
Normal random vector
A real random vector is called a normal random vector if there exists a random -vector , which is a standard normal random vector, a -vector , and a matrix , such that .
Formally:
Here the covariance matrix is .
In the degenerate case where the covariance matrix is singular, the corresponding distribution has no density; see the section below for details. This case arises frequently in statistics; for example, in the distribution of the vector of residuals in the ordinary least squares regression. The are in general not independent; they can be seen as the result of applying the matrix to a collection of independent Gaussian variables .
Equivalent definitions
The following definitions are equivalent to the definition given above. A random vector has a multivariate normal distribution if it satisfies one of the following equivalent conditions.
- Every linear combination of its components is normally distributed. That is, for any constant vector , the random variable has a univariate normal distribution, where a univariate normal distribution with zero variance is a point mass on its mean.
- There is a k-vector and a symmetric, positive semidefinite matrix , such that the characteristic function of is
The spherical normal distribution can be characterised as the unique distribution where components are independent in any orthogonal coordinate system.
Density function
Non-degenerate case
The multivariate normal distribution is said to be "non-degenerate" when the symmetric covariance matrix is positive definite. In this case the distribution has density
where is a real k-dimensional column vector and is the determinant of , also known as the generalized variance. The subexpression can be re-written as , which is especially useful in the degenerate case; see below. The equation above reduces to that of the univariate normal distribution if is a matrix (i.e., a single real number).
The circularly symmetric version of the complex normal distribution has a slightly different form.
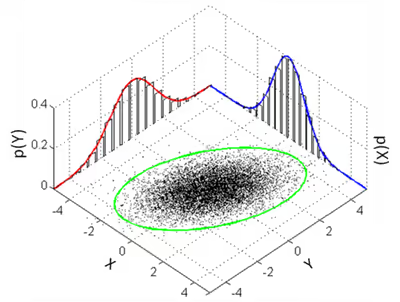
Each iso-density locus — the locus of points in k-dimensional space each of which gives the same particular value of the density — is an ellipse or its higher-dimensional generalization; hence the multivariate normal is a special case of the elliptical distributions.
The quantity is known as the Mahalanobis distance, which represents the distance of the test point from the mean . The squared Mahalanobis distance is decomposed into a sum of k terms, each term being a product of three meaningful components. Note that in the case when , the distribution reduces to a univariate normal distribution and the Mahalanobis distance reduces to the absolute value of the standard score. See also Interval below.
Bivariate case
In the 2-dimensional nonsingular case (), the probability density function of a vector is: where is the correlation between and and where and . In this case,
In the bivariate case, the first equivalent condition for multivariate reconstruction of normality can be made less restrictive as it is sufficient to verify that a countably infinite set of distinct linear combinations of and are normal in order to conclude that the vector of is bivariate normal.
The bivariate iso-density loci plotted in the -plane are ellipses, whose principal axes are defined by the eigenvectors of the covariance matrix (the major and minor semidiameters of the ellipse equal the square-root of the ordered eigenvalues).
As the absolute value of the correlation parameter increases, these loci are squeezed toward the following line :
This is because this expression, with (where sgn is the sign function) replaced by , is the best linear unbiased prediction of given a value of .
Degenerate case
If the covariance matrix is not full rank, then the multivariate normal distribution is degenerate and does not have a density. More precisely, it does not have a density with respect to k-dimensional Lebesgue measure (which is the usual measure assumed in calculus-level probability courses). Only random vectors whose distributions are absolutely continuous with respect to a measure are said to have densities (with respect to that measure). To talk about densities but avoid dealing with measure-theoretic complications it can be simpler to restrict attention to a subset of of the coordinates of such that the covariance matrix for this subset is positive definite; then the other coordinates may be thought of as an affine function of these selected coordinates.
To talk about densities meaningfully in singular cases, then, we must select a different base measure. Using the disintegration theorem we can define a restriction of Lebesgue measure to the -dimensional affine subspace of where the Gaussian distribution is supported, i.e. . With respect to this measure the distribution has the density of the following motif:
where is the generalized inverse and is the pseudo-determinant.
Cumulative distribution function
The notion of cumulative distribution function (cdf) in dimension 1 can be extended in two ways to the multidimensional case, based on rectangular and ellipsoidal regions.
The first way is to define the cdf of a random vector as the probability that all components of are less than or equal to the corresponding values in the vector :
Though there is no closed form for , there are a number of algorithms that estimate it numerically.
Another way is to define the cdf as the probability that a sample lies inside the ellipsoid determined by its Mahalanobis distance from the Gaussian, a direct generalization of the standard deviation. In order to compute the values of this function, closed analytic formula exist, as follows.
Interval
The interval for the multivariate normal distribution yields a region consisting of those vectors x satisfying
Here is a -dimensional vector, is the known -dimensional mean vector, is the known covariance matrix and is the quantile function for probability of the chi-squared distribution with degrees of freedom. When the expression defines the interior of an ellipse and the chi-squared distribution simplifies to an exponential distribution with mean equal to two (rate equal to half).
Complementary cumulative distribution function (tail distribution)
The complementary cumulative distribution function (ccdf) or the tail distribution is defined as . When , then the ccdf can be written as a probability the maximum of dependent Gaussian variables:
While no simple closed formula exists for computing the ccdf, the maximum of dependent Gaussian variables can be estimated accurately via the Monte Carlo method.
Sign in to keep reading
3 more chapters are free with a Lably account.
Properties
Moments
The kth-order moments of x are given by
where r1 + r2 + ⋯ + rN = k.
The kth-order central moments are as follows
- If k is odd, μ1, ..., N(x − μ) = 0.
- If k is even with k = 2λ, then
where the sum is taken over all allocations of the set into λ (unordered) pairs. That is, for a kth (= 2λ = 6) central moment, one sums the products of λ = 3 covariances (the expected value μ is taken to be 0 in the interests of parsimony):
This yields terms in the sum (15 in the above case), each being the product of λ (in this case 3) covariances. For fourth order moments (four variables) there are three terms. For sixth-order moments there are 3 × 5 = 15 terms, and for eighth-order moments there are 3 × 5 × 7 = 105 terms.
The covariances are then determined by replacing the terms of the list by the corresponding terms of the list consisting of r1 ones, then r2 twos, etc.. To illustrate this, examine the following 4th-order central moment case:
where is the covariance of Xi and Xj. With the above method one first finds the general case for a kth moment with k different X variables, , and then one simplifies this accordingly. For example, for , one lets Xi = Xj and one uses the fact that .
Functions of a normal vector
A quadratic form of a normal vector , (where is a matrix, is a vector, and is a scalar), is a generalized chi-squared variable. The direction of a normal vector follows a projected normal distribution.
If is a general scalar-valued function of a normal vector, its probability density function, cumulative distribution function, and inverse cumulative distribution function can be computed with the numerical method of ray-tracing (Matlab code Archived 2025-02-20 at the Wayback Machine).
Likelihood function
If the mean and covariance matrix are known, the log likelihood of an observed vector is simply the log of the probability density function:
- ,
The circularly symmetric version of the noncentral complex case, where is a vector of complex numbers, would be
i.e. with the conjugate transpose (indicated by ) replacing the normal transpose (indicated by ). This is slightly different than in the real case, because the circularly symmetric version of the complex normal distribution has a slightly different form for the normalization constant.
A similar notation is used for multiple linear regression.
Since the log likelihood of a normal vector is a quadratic form of the normal vector, it is distributed as a generalized chi-squared variable.
Differential entropy
The differential entropy of the multivariate normal distribution is
where the bars denote the matrix determinant, k is the dimensionality of the vector space, and the result has units of nats.
Kullback–Leibler divergence
The Kullback–Leibler divergence from to , for non-singular matrices Σ1 and Σ0, is:
where denotes the matrix determinant, is the trace, is the natural logarithm and is the dimension of the vector space.
The logarithm must be taken to base e since the two terms following the logarithm are themselves base-e logarithms of expressions that are either factors of the density function or otherwise arise naturally. The equation therefore gives a result measured in nats. Dividing the entire expression above by loge 2 yields the divergence in bits.
When ,
Mutual information
The mutual information of two multivariate normal distribution is a special case of the Kullback–Leibler divergence in which is the full dimensional multivariate distribution and is the product of the and dimensional marginal distributions and , such that . The mutual information between and is given by:
where
If is product of one-dimensional normal distributions, then in the notation of the Kullback–Leibler divergence section of this article, is a diagonal matrix with the diagonal entries of , and . The resulting formula for mutual information is:
where is the correlation matrix constructed from .
In the bivariate case the expression for the mutual information is:
Joint normality
Normally distributed and independent
If and are normally distributed and independent, this implies they are "jointly normally distributed", i.e., the pair must have multivariate normal distribution. However, a pair of jointly normally distributed variables need not be independent (would only be so if uncorrelated, ).
Two normally distributed random variables need not be jointly bivariate normal
The fact that two random variables and both have a normal distribution does not imply that the pair has a joint normal distribution. A simple example is one in which has a normal distribution with expected value 0 and variance 1, and if and if , where . There are similar counterexamples for more than two random variables. In general, they sum to a mixture model.
Correlations and independence
In general, random variables may be uncorrelated but statistically dependent. But if a random vector has a multivariate normal distribution then any two or more of its components that are uncorrelated are independent. This implies that any two or more of its components that are pairwise independent are independent. But, as pointed out just above, it is not true that two random variables that are (separately, marginally) normally distributed and uncorrelated are independent.
Conditional distributions
If N-dimensional x is partitioned as follows
and accordingly μ and Σ are partitioned as follows
then the distribution of x1 conditional on x2 = a is multivariate normal (x1 | x2 = a) ~ N(μ, Σ) where
and covariance matrix
Here is the generalized inverse of . The matrix is the Schur complement of Σ22 in Σ. That is, the equation above is equivalent to inverting the overall covariance matrix, dropping the rows and columns corresponding to the variables being conditioned upon, and inverting back to get the conditional covariance matrix.
Note that knowing that x2 = a alters the variance, though the new variance does not depend on the specific value of a; perhaps more surprisingly, the mean is shifted by ; compare this with the situation of not knowing the value of a, in which case x1 would have distribution .
An interesting fact derived in order to prove this result, is that the random vectors and are independent.
The matrix Σ12Σ22−1 is known as the matrix of regression coefficients.
Bivariate case
In the bivariate case where x is partitioned into and , the conditional distribution of given is
where is the correlation coefficient between and .
Bivariate conditional expectation, centered case with unit variances
The conditional expectation of X1 given X2 is
and the conditional variance is
thus the conditional variance does not depend on x2.
The conditional expectation of X1 given that X2 is smaller/bigger than z is:
where the final ratio here is called the inverse Mills ratio.
Proof: the last two results are obtained using the result , so that
- and then using the properties of the expectation of a truncated normal distribution.
Marginal distributions
To obtain the marginal distribution over a subset of multivariate normal random variables, one only needs to drop the irrelevant variables (the variables that one wants to marginalize out) from the mean vector and the covariance matrix. The proof for this follows from the definitions of multivariate normal distributions and linear algebra.
Example
Let X = [X1, X2, X3] be multivariate normal random variables with mean vector μ = [μ1, μ2, μ3] and covariance matrix Σ (standard parametrization for multivariate normal distributions). Then the joint distribution of X′ = [X1, X3] is multivariate normal with mean vector μ′ = [μ1, μ3] and covariance matrix .
Affine transformation
If Y = c + BX is an affine transformation of where c is an vector of constants and B is a constant matrix, then Y has a multivariate normal distribution with expected value c + Bμ and variance BΣBT i.e., . In particular, any subset of the Xi has a marginal distribution that is also multivariate normal. To see this, consider the following example: to extract the subset (X1, X2, X4)T, use
which extracts the desired elements directly.
Another corollary is that the distribution of Z = b · X, where b is a constant vector with the same number of elements as X and the dot indicates the dot product, is univariate Gaussian with . This result follows by using
Observe how the positive-definiteness of Σ implies that the variance of the dot product must be positive.
An affine transformation of X such as 2X is not the same as the sum of two independent realisations of X.
Geometric interpretation
The equidensity contours of a non-singular multivariate normal distribution are ellipsoids (i.e. affine transformations of hyperspheres) centered at the mean. Hence the multivariate normal distribution is an example of the class of elliptical distributions. The directions of the principal axes of the ellipsoids are given by the eigenvectors of the covariance matrix . The squared relative lengths of the principal axes are given by the corresponding eigenvalues.
If Σ = UΛUT = UΛ1/2(UΛ1/2)T is an eigendecomposition where the columns of U are unit eigenvectors and Λ is a diagonal matrix of the eigenvalues, then we have
Moreover, U can be chosen to be a rotation matrix, as inverting an axis does not have any effect on N(0, Λ), but inverting a column changes the sign of U's determinant. The distribution N(μ, Σ) is in effect N(0, I) scaled by Λ1/2, rotated by U and translated by μ.
Conversely, any choice of μ, full rank matrix U, and positive diagonal entries Λi yields a non-singular multivariate normal distribution. If any Λi is zero and U is square, the resulting covariance matrix UΛUT is singular. Geometrically this means that every contour ellipsoid is infinitely thin and has zero volume in n-dimensional space, as at least one of the principal axes has length of zero; this is the degenerate case.
"The radius around the true mean in a bivariate normal random variable, re-written in polar coordinates (radius and angle), follows a Hoyt distribution."
In one dimension the probability of finding a sample of the normal distribution in the interval is approximately 68.27%, but in higher dimensions the probability of finding a sample in the region of the standard deviation ellipse is lower.
Statistical inference
Parameter estimation
The derivation of the maximum-likelihood estimator of the covariance matrix of a multivariate normal distribution is straightforward.
In short, the probability density function (pdf) of a multivariate normal is
and the ML estimator of the covariance matrix from a sample of n observations is
which is simply the sample covariance matrix. This is a biased estimator whose expectation is
An unbiased sample covariance is
- (matrix form; is the identity matrix, J is a matrix of ones; the term in parentheses is thus the centering matrix)
The Fisher information matrix for estimating the parameters of a multivariate normal distribution has a closed form expression. This can be used, for example, to compute the Cramér–Rao bound for parameter estimation in this setting. See Fisher information for more details.
Bayesian inference
In Bayesian statistics, the conjugate prior of the mean vector is another multivariate normal distribution, and the conjugate prior of the covariance matrix is an inverse-Wishart distribution . Suppose then that n observations have been made
and that a conjugate prior has been assigned, where
where
and
Then
where
Multivariate normality tests
Multivariate normality tests check a given set of data for similarity to the multivariate normal distribution. The null hypothesis is that the data set is similar to the normal distribution, therefore a sufficiently small p-value indicates non-normal data. Multivariate normality tests include the Cox–Small test and Smith and Jain's adaptation of the Friedman–Rafsky test created by Larry Rafsky and Jerome Friedman.
Mardia's test
Mardia's test is based on multivariate extensions of skewness and kurtosis measures. For a sample {x1, ..., xn} of k-dimensional vectors we compute
Under the null hypothesis of multivariate normality, the statistic A will have approximately a chi-squared distribution with 1/6⋅k(k + 1)(k + 2) degrees of freedom, and B will be approximately standard normal N(0,1).
Mardia's kurtosis statistic is skewed and converges very slowly to the limiting normal distribution. For medium size samples , the parameters of the asymptotic distribution of the kurtosis statistic are modified For small sample tests () empirical critical values are used. Tables of critical values for both statistics are given by Rencher for k = 2, 3, 4.
Mardia's tests are affine invariant but not consistent. For example, the multivariate skewness test is not consistent against symmetric non-normal alternatives.
BHEP test
The BHEP test computes the norm of the difference between the empirical characteristic function and the theoretical characteristic function of the normal distribution. Calculation of the norm is performed in the L2(μ) space of square-integrable functions with respect to the Gaussian weighting function . The test statistic is
The limiting distribution of this test statistic is a weighted sum of chi-squared random variables.
A detailed survey of these and other test procedures is available.
Computational methods
Drawing values from the distribution
A widely used method for drawing (sampling) a random vector x from the N-dimensional multivariate normal distribution with mean vector μ and covariance matrix Σ works as follows:
- Find any real matrix A such that AAT = Σ. When Σ is positive-definite, the Cholesky decomposition is typically used because it is widely available, computationally efficient, and well known. If a rank-revealing (pivoted) Cholesky decomposition such as LAPACK's dpstrf() is available, it can be used in the general positive-semidefinite case as well. A slower general alternative is to use the matrix A = UΛ1/2 obtained from a spectral decomposition Σ = UΛU−1 of Σ.
- Let z = (z1, ..., zN)T be a vector whose components are N independent standard normal variates (which can be generated, for example, by using the Box–Muller transform).
- Let x be μ + Az. This has the desired distribution due to the affine transformation property.